I am Chuyue Li, and I work on agents that improve themselves.
My research centers on recursive self-improvement, self- and co-evolving agents and agentic RL — applied to video, image, game and code.
Currently a first-year MSCS student at the University of Illinois Urbana-Champaign, after a CS undergraduate degree at ShanghaiTech University and a junior-year exchange at UC Berkeley. I have been a research intern at Alibaba Qwen and Tencent Hunyuan, and a research assistant at the ShanghaiTech VDI Center.
Directions I have worked on:
- Self-evolving agents for cinematic-grade video representation learning — first-author work in the AIGC team at Alibaba Qwen.
- Agentic RL for long-horizon creative planning and tool use — research intern in the Multimodal Model Department at Tencent Hunyuan.
- Multimodal time series conditional diffusion generation, and LLMs for code and coding agents.
- Recursive self-improvement
- Self- & co-evolving agents
- Agentic RL
- Long-horizon planning & tool use
- Multimodal generation
- Evaluation & reward design
News
PyMETA accepted to NeurIPS 2026 TAE.
Started my MSCS at UIUC, on the research track.
Wrapped up my research internship with the AIGC team at Alibaba Qwen.
VisionCreator accepted to CVPR 2026 Findings.
VerbalTS: Generating Time Series from Texts accepted to ICML 2025.
Completed a junior exchange year at UC Berkeley.
Publications & Manuscripts
My name in bold. * denotes equal contribution.
-
 Under review
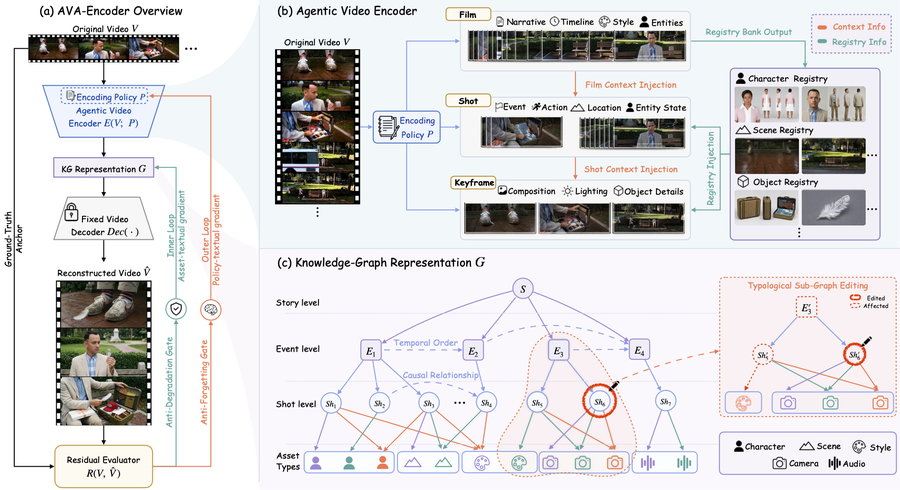
AVA-Encoder: Towards Agent-Native Video Representation Learning
A self-evolving agentic auto-encoder that learns editable, agent-native structured representations from cinematic-grade video through reconstruction-based self-supervision. 49.0% reconstruction fidelity (+20.7 pts over the strongest baseline) with over 70% fewer system-prompt tokens.
Self-evolving agents · RSI · Agentic learning · Video representation · Visual evaluation
-
 CVPR 2026
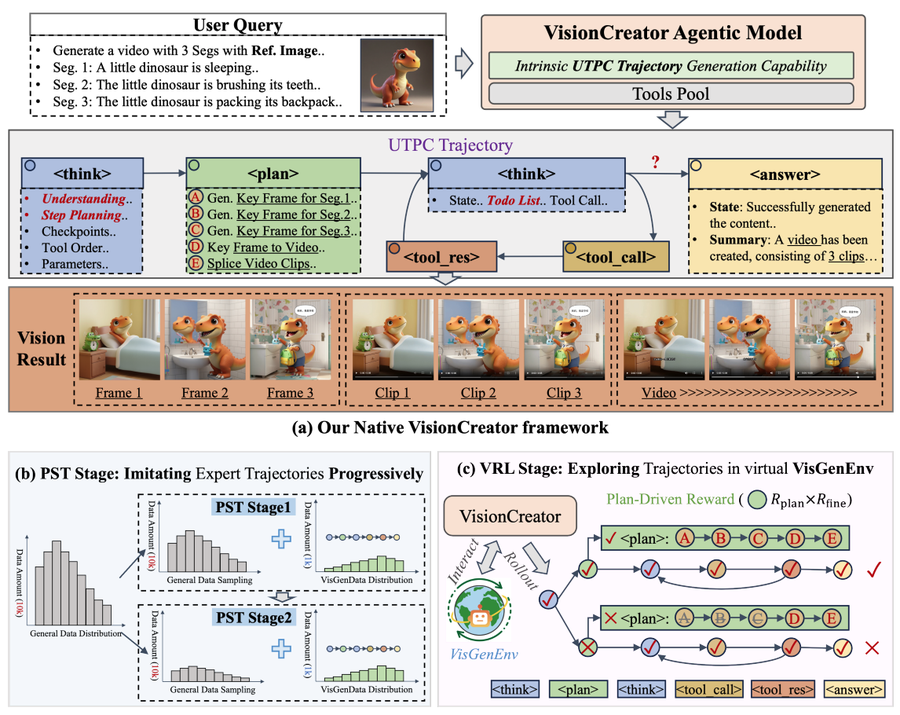
VisionCreator: A Native Visual-Generation Agentic Model with Understanding, Thinking, Planning and Creation
Accepted to CVPR 2026 Findings. A native multimodal agent for creative image and video generation, with long-horizon hierarchical planning and dynamic tool calling across 20+ step trajectories.
Agentic RL · GRPO · Planning & tool call · Composite reward · Visual feedback
-
NeurIPS 2026 TAE
PyMETA: Evaluating Student Code Diagnosis on and Beyond the First Execution Error
A multi-level taxonomy and 40,000-error benchmark for student Python code, with single- and multi-error detection across seven model architectures.
LLM for code understanding · Educational AI · Code error analysis · Benchmarking
-
Under review
EvoScript: Reinforcement Learning for Script Generation with Evolving Rubrics
GRPO · Self-evolution · RSI · Creative script generation
-
 ICML 2025
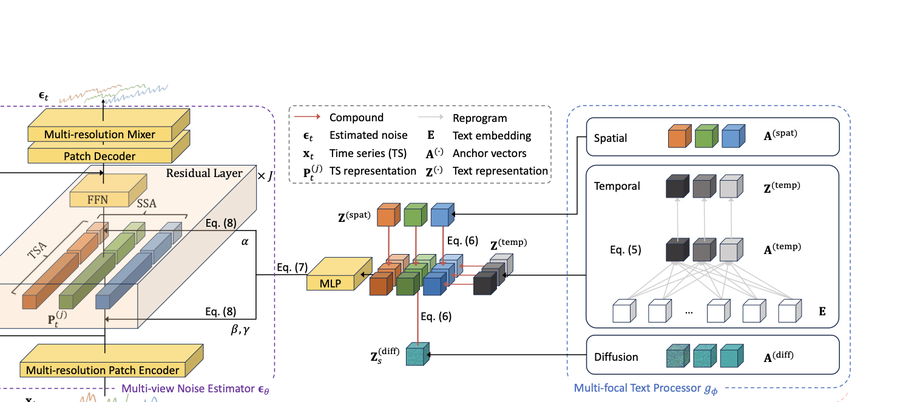
VerbalTS: Generating Time Series from Texts
A multi-focal framework for fine-grained cross-modal alignment and controllable text-to-time-series generation, validated on 6 datasets. FID, J-FTSD and CTTP improved by 20%+ over strong baselines, with up to 58.7% lower FID.
Conditional diffusion · Multimodal generation · Modality alignment · Time series modeling
-
 Under review
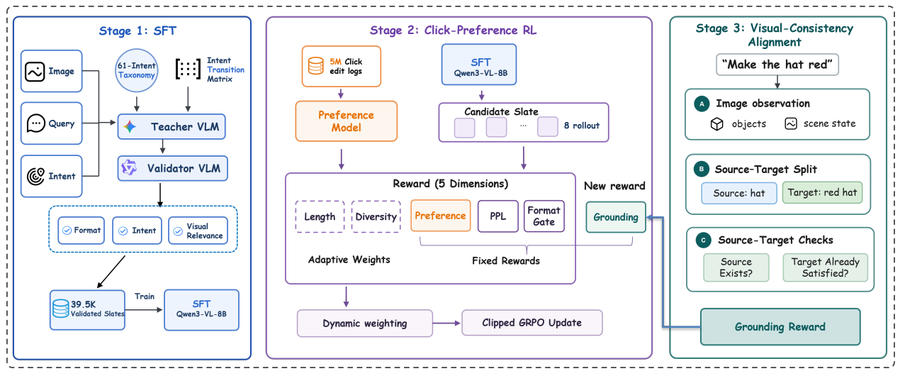
What to Edit Next: Visually Aligned Image-Editing Follow-Up Suggestions in Conversational Systems
Agentic RL · Interactive image editing · Multimodal understanding · Visual recommendation
-
Under review
Learning to Simulate Individuals from Macro Social Signals
Reinforcement learning · User simulation · Social modeling · LLM forecasting · Collective intelligence
-
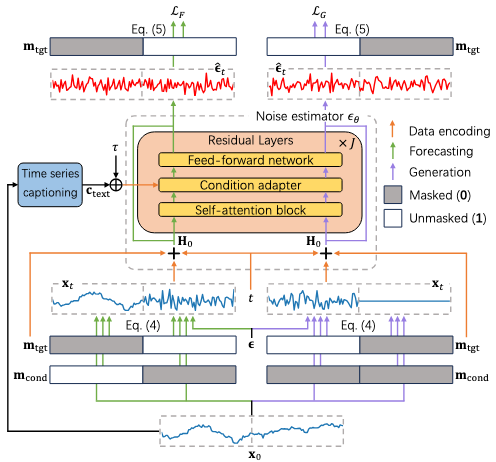 Under review
Unified Generative Modeling for Multimodal Time Series Analysis
GenTS casts conditional generation, forecasting and editing as one masked-conditional generation problem under a shared noise estimator.
Multimodal learning · Unified generative modeling · Forecasting / generation / editing
Research Experience
-
Self-Evolving Agent for Cinematic-Grade Video Representation Learning
Visual Technology Dept., AIGC Team · Mentors: Jinpeng Yu, Jiaming Liu
- Developed a self-evolving agentic auto-encoder that learns editable, agent-native structured representations from cinematic-grade video through reconstruction-based self-supervision — without ground-truth graphs or expert creation trajectories.
- Built a hierarchical agentic encoder spanning video, shot and keyframe levels with cross-level context injection, and confidence-aware visual feedback that localizes reconstruction errors and distills them into actionable textual gradients.
- Designed gated dual-loop self-evolution: an outer loop that pseudo-trains transferable policies behind a replay-based anti-forgetting gate, and an inner loop that refines representations at test time behind an anti-degradation gate.
- Reached 49.0% reconstruction fidelity (+20.7 pts over the strongest baseline); the self-evolved policy beat a human-engineered one (45.8 vs. 44.4) with over 70% fewer system-prompt tokens, and dual-loop evolution added 6.6 pts over the initial policy.
-
Agentic RL for Long-Horizon Hierarchical Creative Planning and Tool Use
Multimodal Model Dept., Visual Agent Team · Mentor: Rongwei Quan
- Built a native multimodal agent for creative image and video generation — storytelling, commercials, music videos, education, VFX and film — with long-horizon hierarchical planning, dynamic tool calling and adaptive execution across 20+ step trajectories.
- Designed two-stage Progressive Specialization Training, shifting training toward visual creation while retaining general data to prevent catastrophic forgetting.
- Developed a two-stage GRPO agentic RL pipeline for expensive, long-latency generation tools: virtual RL in a 36-tool simulated environment to learn planning and tool-use policies without costly real rollouts, then online GRPO on real multimodal tool interactions.
- Designed plan-driven trajectory rewards over expert-guided plan evaluation, tool-call validity, execution coherence and goal achievement, with confidence-aware VLM evaluation and visual self-reflection.
- Raised the pre-RL reward from 0.64 to 0.87 and accelerated RL convergence by ~50%; +49% overall score over the strongest baseline, and a 3.42 human score against GPT-5’s 3.19 and Gemini-2.5-Pro’s 3.01.
-
LLMs for Multi-level Coding Error Classification
Supervisors: Kazuma Hashimoto, Lingyu Gao · NeurIPS 2026 TAE
- Designed a fine-grained, multi-level taxonomy of Python error types for web-based online compilers, and built a benchmark over 40,000 real-world errors covering single- and multi-error cases.
- Improved multi-level detection through fine-tuning and prompting, leveraging real error patterns and unstructured debugging logs.
- Analyzed bias, capability limits and confidence across seven model architectures under increasing error granularity.
-
Multimodal Time Series Conditional Generation from Unstructured Text
Supervisor: Kan Ren · ICML 2025
- Designed a multi-focal framework for finer-grained cross-modal semantic alignment and controllable time-series generation from unstructured text, validated on 6 synthetic and real-world datasets.
- Implemented a multi-view noise estimator performing multi-resolution modelling and noise estimation across temporal, spatial and diffusion perspectives, for 20%+ fidelity gains.
- Proposed a multi-focal text processor that decomposes text embeddings across temporal resolutions, spatial variables and diffusion stages, using learnable anchor vectors and semantic reprogramming.
- Built an adapter for progressive, hierarchical cross-modal control, cutting Weather J-FTSD from 18.33 to 8.56.
- Proposed the CTTP model and CTTP Score; improved FID, J-FTSD and CTTP by 20%+ over strong baselines, with up to 58.7% lower FID.
-
Unified Model for Multimodal Time Series Generation, Prediction and Editing
Supervisor: Kan Ren
- Proposed GenTS, unifying conditional generation, forecasting and editing as a single masked-conditional generation problem.
- Designed a unified noise estimator for cross-task generation and adaptive multimodal time series modeling.
- Introduced domain-agnostic automated time series captioning from statistical and morphological features, addressing the scarcity of paired multimodal data.
Education
-
2026.08 — 2028.06
University of Illinois Urbana-Champaign
M.S. in Computer Science, Research Track · first year
-
2024.08 — 2025.05
University of California, Berkeley
Computer Science, junior exchange
-
2022.09 — 2026.06
ShanghaiTech University
B.S. in Computer Science